PROCESS
1. Creating the Dataset
The majority of our time was spent creating a usable dataset for our analyses. Our main dataset provided to us by David Bliss, was messy and contained information that was not relevant to our analyses. Therefore, the first step was to export the entire csv dataset to RStudio and select the key variables of interest which were: program title, performance date, program transcript, and the identifier.
One issue with the format was the values in the Title column. The page numbers each took an individual row and also had the variable that contained the transcribed text for the respective page, which was then followed by a row containing the actual title of the program and the respective date and identifier.
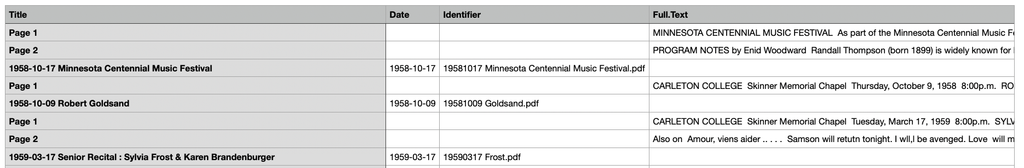
Using online resources for help with coding in R including cheatsheets created by Posit and Google Gemini, we were able to alter the dataset so that each program only took one row, and the page numbers became separate columns for each row.
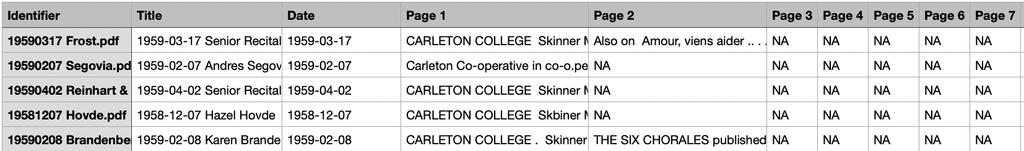
Then, we used R to filter for only Junior and Senior Recitals, and to extract the year from each date.
Then, using Google Sheets, we extracted all the piece titles and respective composers for each row alongside the main soloist instrument. One issue we ran into was that some of the composer names were formatted differently across programs. For example, some programs wrote “Wolfgang Amadeus Mozart” and others wrote “W.A. Mozart”, or “Debussy” vs. “Claude Debussy”. Therefore, in order to standardize the names after we finished inputting the data, we used OpenRefine and its clustering function to easily fix some of these formatting issues or small spelling mistakes that showed up. We also used Google Sheets and the find and replace function to fix issues that OpenRefine could not identify.
After creating our dataset with Performance Year, Performer’s Grade, Instrument, Piece, and Composer, we then researched the composer’s respective birth country, city/state, and birth year. We decided to manually enter this data as we could not find another method that is more efficient. After this information was input, our dataset was ready to be used for analysis.

2. Creating the Visualizations and Presentation Choices
We chose to visualize our data using Flourish as we wanted to create a timeline. Add more once visualizations are created.